K AVAILABLE

HEY, I'M KAUSHIK šŸ‘‹

I build AI-powered systems that solve
real problems.

I combine AI engineering with backend expertise to build scalable systems, experiment with modern models, and share everything I learn.

End-to-End AI System Architecture SYSTEM READY
Clients
šŸ’»Web App
šŸ“±Mobile App
ā˜ļøAPI Clients
⬔API GatewayRate Limiting & Auth
AI Service Layer
šŸ›”ļø
Auth ServiceJWT & Session RBAC
⚔
Inference ServiceLocal & Cloud LLMs
šŸ”„
Task OrchestratorTool Calls & Reasoning
Messaging / Queue
šŸ“ØKafka / Redis Streams
Data Layer
šŸ—„ļøPostgreSQL
šŸŽÆVector DB (Milvus)
⚔Redis Cache
šŸ“¦Object Storage (S3)
AI SystemsBackend SystemsScalable APIsData Engineering
DockerKubernetesCI/CD (GitHub Actions)Monitoring (Prometheus + Grafana)
šŸš€
3+Production Systems
⚔
780+DSA Problems Solved
šŸ“Š
1.55M+Records Queried
šŸ“
7+Technical Articles
šŸ› ļø
2+Years Building

Latest knowledge

View all posts
No lab experiments recorded yet. Add experiments in experiments.json.
No videos recorded yet. Add video links in videos.json.

Learning journey

2026CURRENT

Agentic AI & Production Distributed Systems

Building enterprise multi-agent workflows, tool use, eval frameworks, and low-latency inference pipelines.

2025

Advanced LLMs & Context Engineering

Specialized in advanced RAG, graph retrieval, AST safety validation, and Model Context Protocol (MCP).

2024

System Design & Backend Architecture at Scale

Mastered high-concurrency event-driven systems, Kafka, Redis caching layers, and cloud native architectures.

2023

Data Engineering & Machine Learning Foundations

Built relational schemas, automated data pipelines, query optimization, and ML model evaluation harness.

2022

Computer Science Foundations & Algorithms

Deep focus on Data Structures & Algorithms, competitive programming (1960+ rating), and OS fundamentals.

DSA & Problem Solving

View profile
Total Solved780+
LeetCode612+
LC Rating1578
CodeChef1501
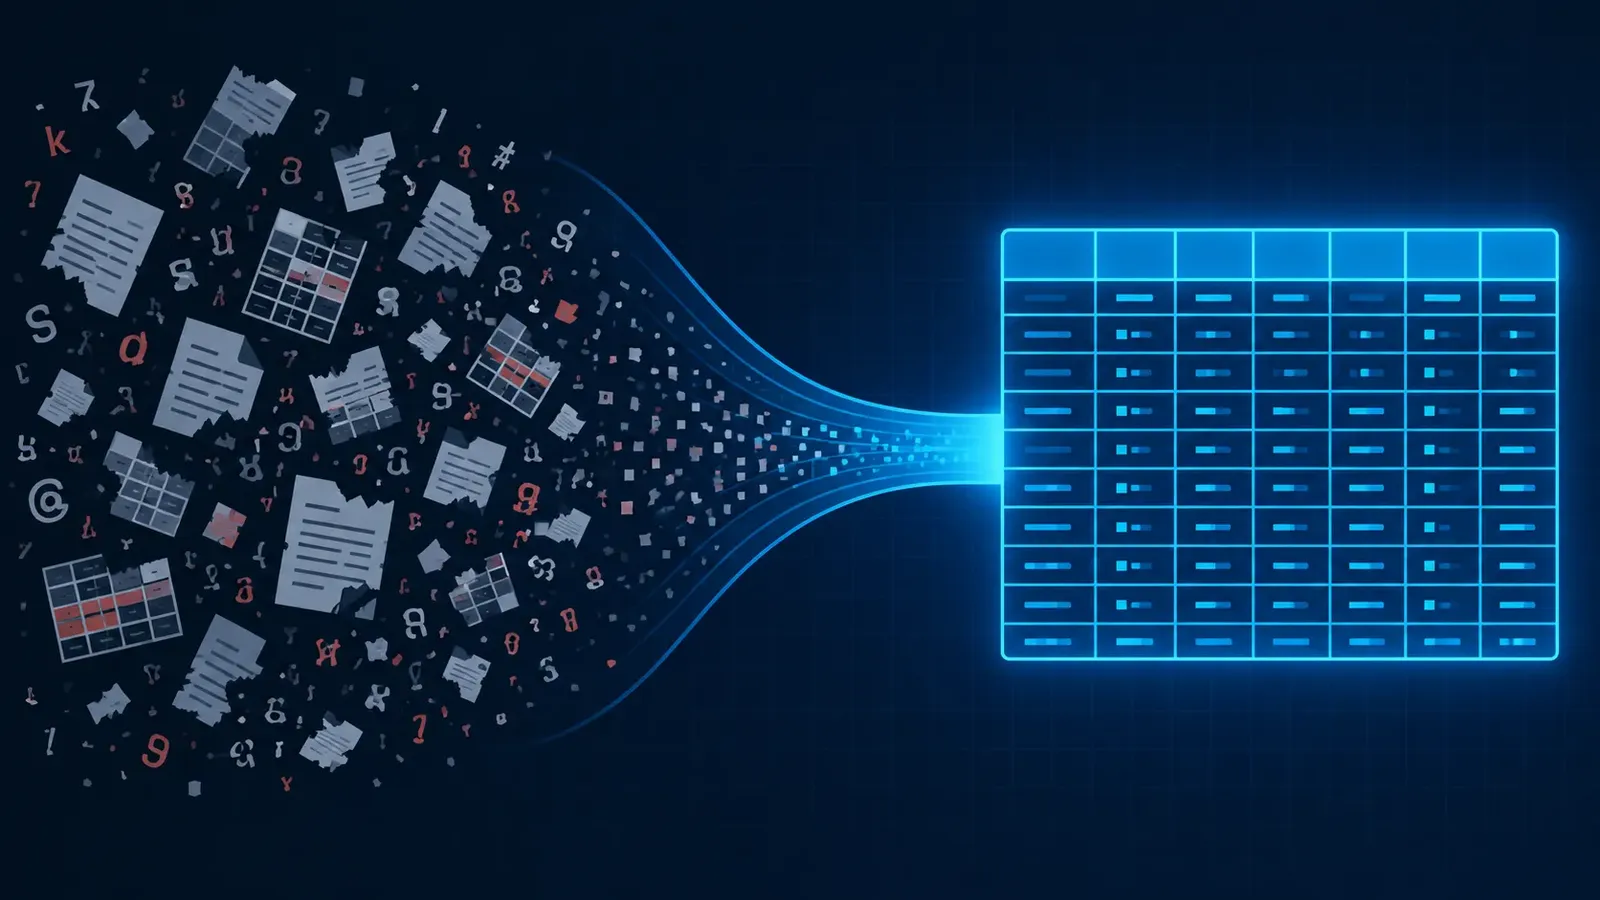
Why 80% of Enterprise RAG Pipelines Fail Cover

Why 80% of Enterprise RAG Pipelines Fail Before They Reach the Vector Database

Scrambled tables, dirty OCR, and orphan chunks quietly poison vector search — here's the four-stage pipeline I use to stop it.

What's inside

  • Architecture principles
  • Data & model pipeline
  • Evaluation & monitoring
  • Deployment & scaling
  • Real-world lessons